Yi (Joshua) Ren
Hey, I am a postdoc at Oxford Applied and Theoretical Machine Learning Group (OATML) led by Prof. Yarin Gal at the University of Oxford. I obtained my Ph.D. in 2025 with Prof. Danica J. Sutherland at the University of British Columbia (UBC). I also visited Prof. Aaron Courville's group at Mila, working on applying iterated learning in general representation learning problems. Before that, I was a master's student at the University of Edinburgh, working with Prof. Simon Kirby and Prof. Shay Cohen on iterated learning and compositional generalization. I also interned at Borealis AI and Cohere , working on time-series learning dynamics and LLMs’ post-training, respectively.
Research
Learning dynamics
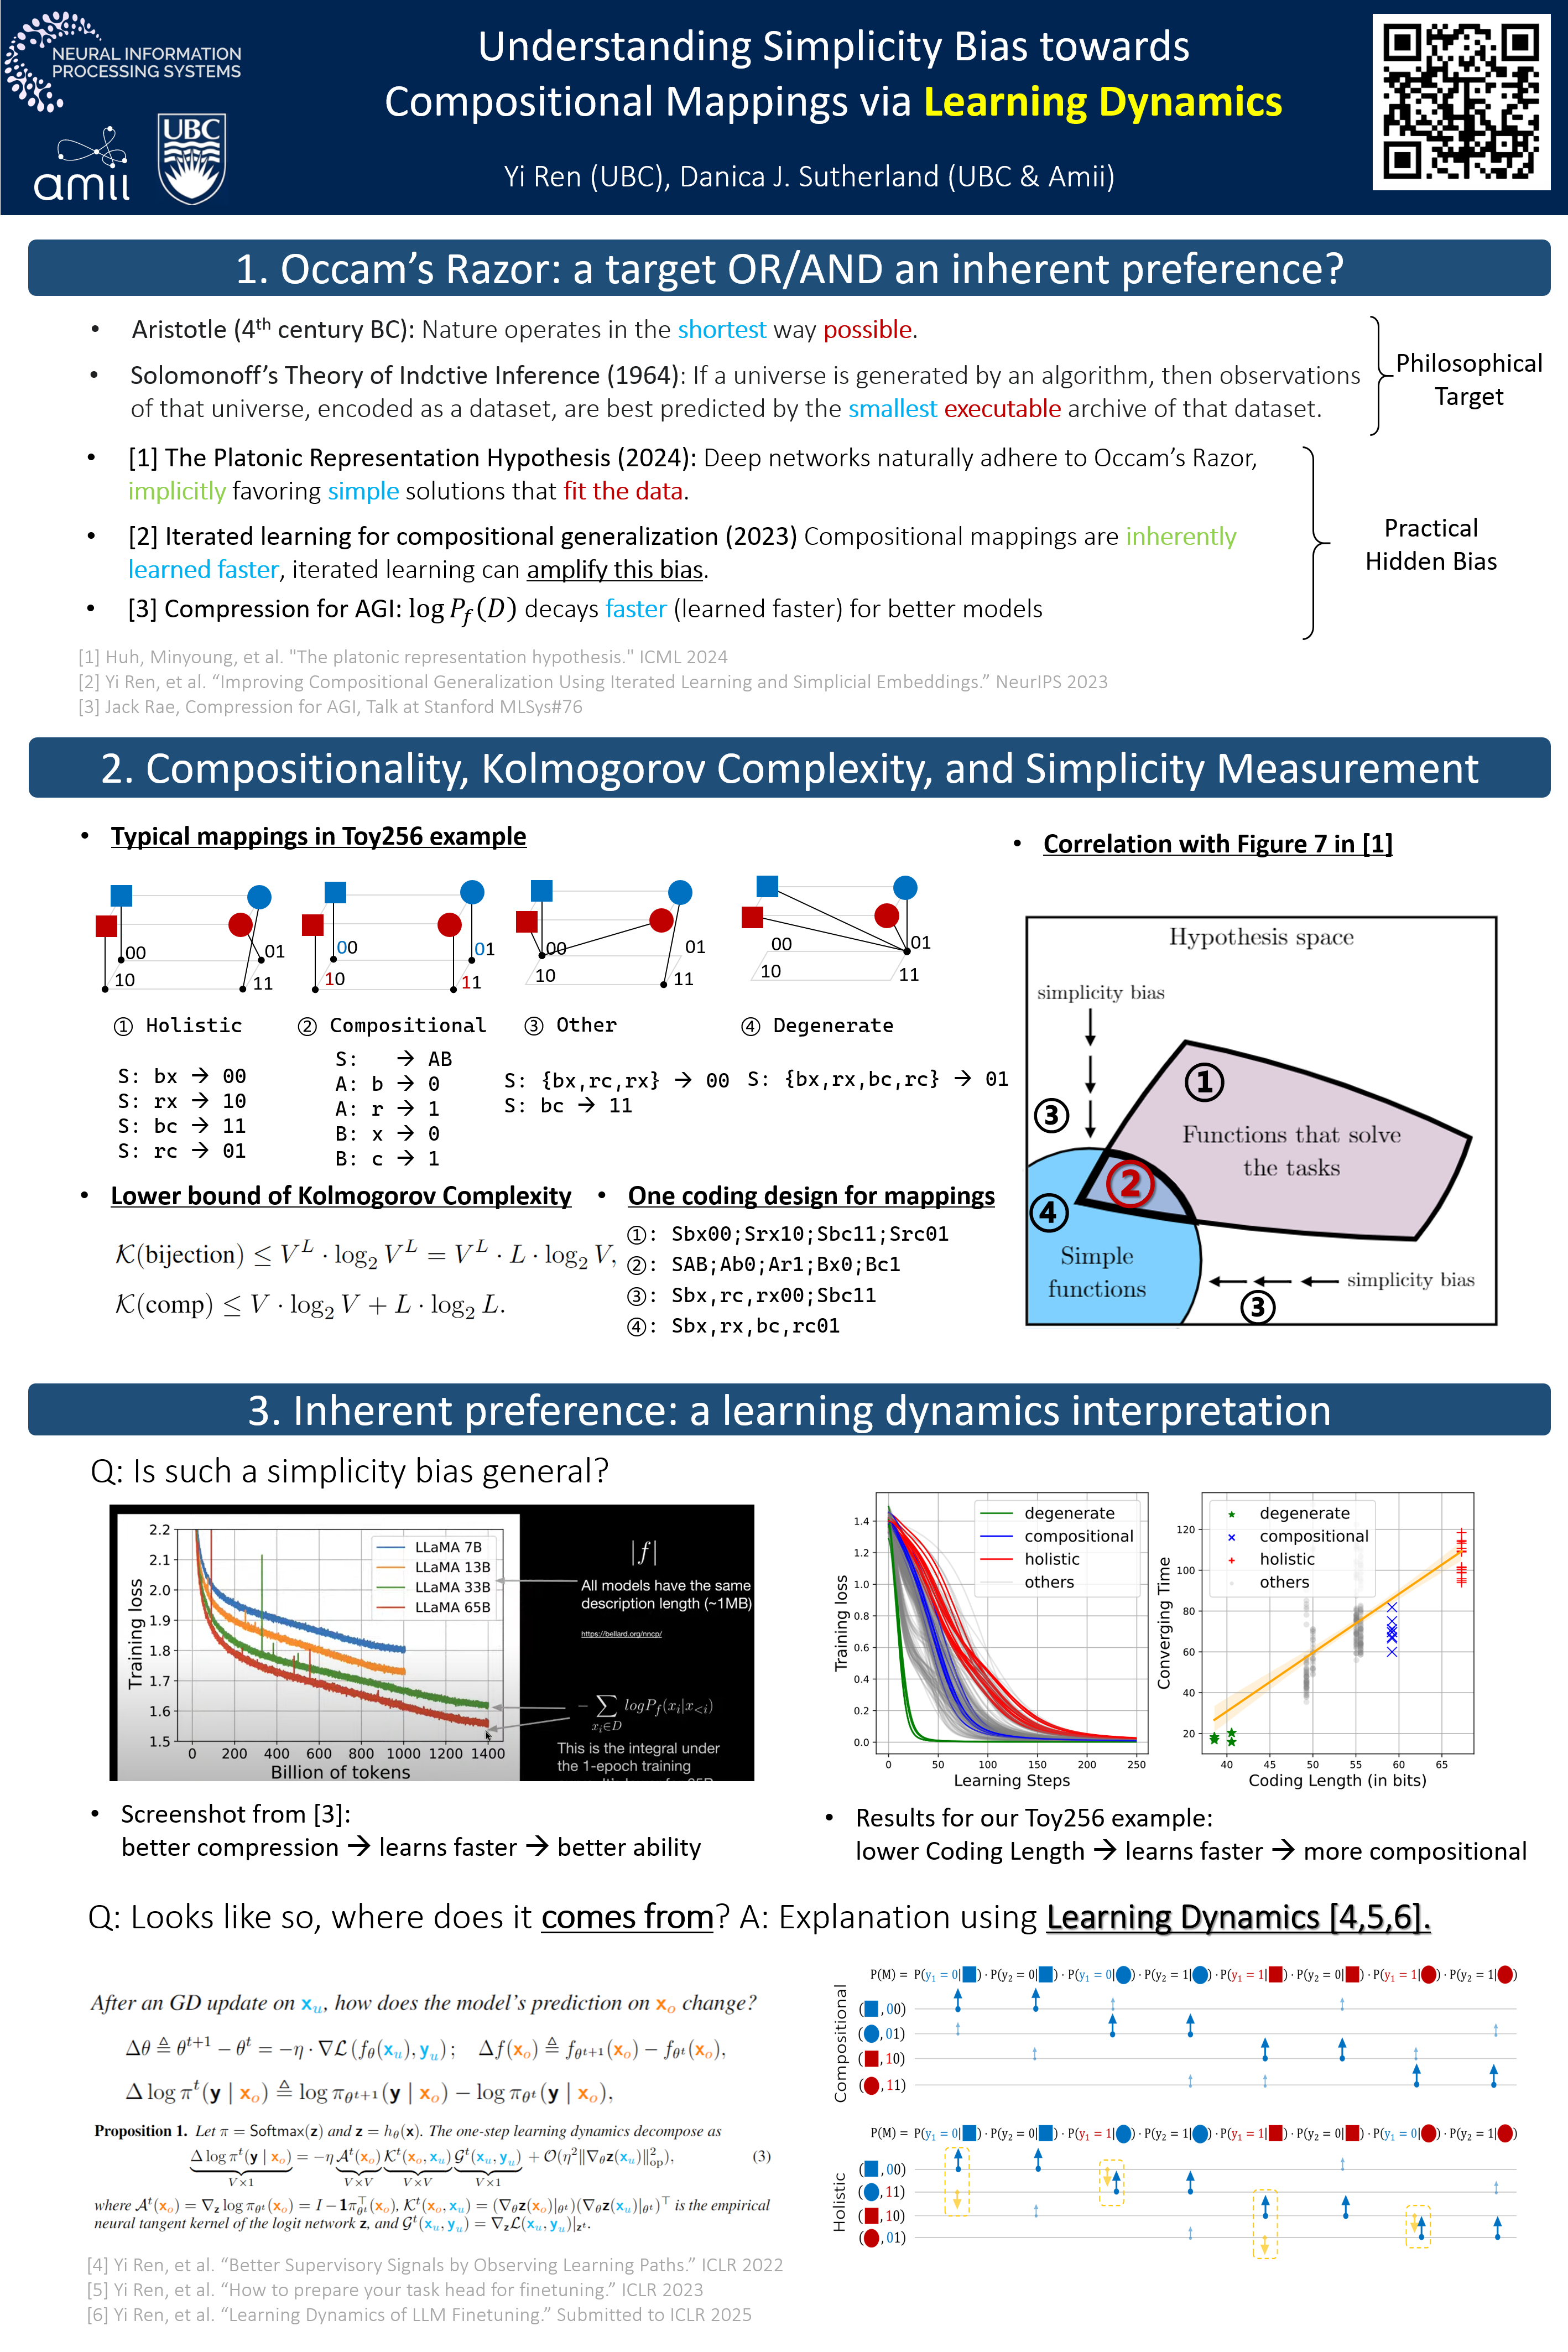
Most of my work is built on learning dynamics: looking at how a model's prediction on one example changes when it learns from another. This turns loose notions like simplicity bias into quantities we can actually measure — learning speed, compression rate — and makes a lot of otherwise puzzling training behaviour tractable.
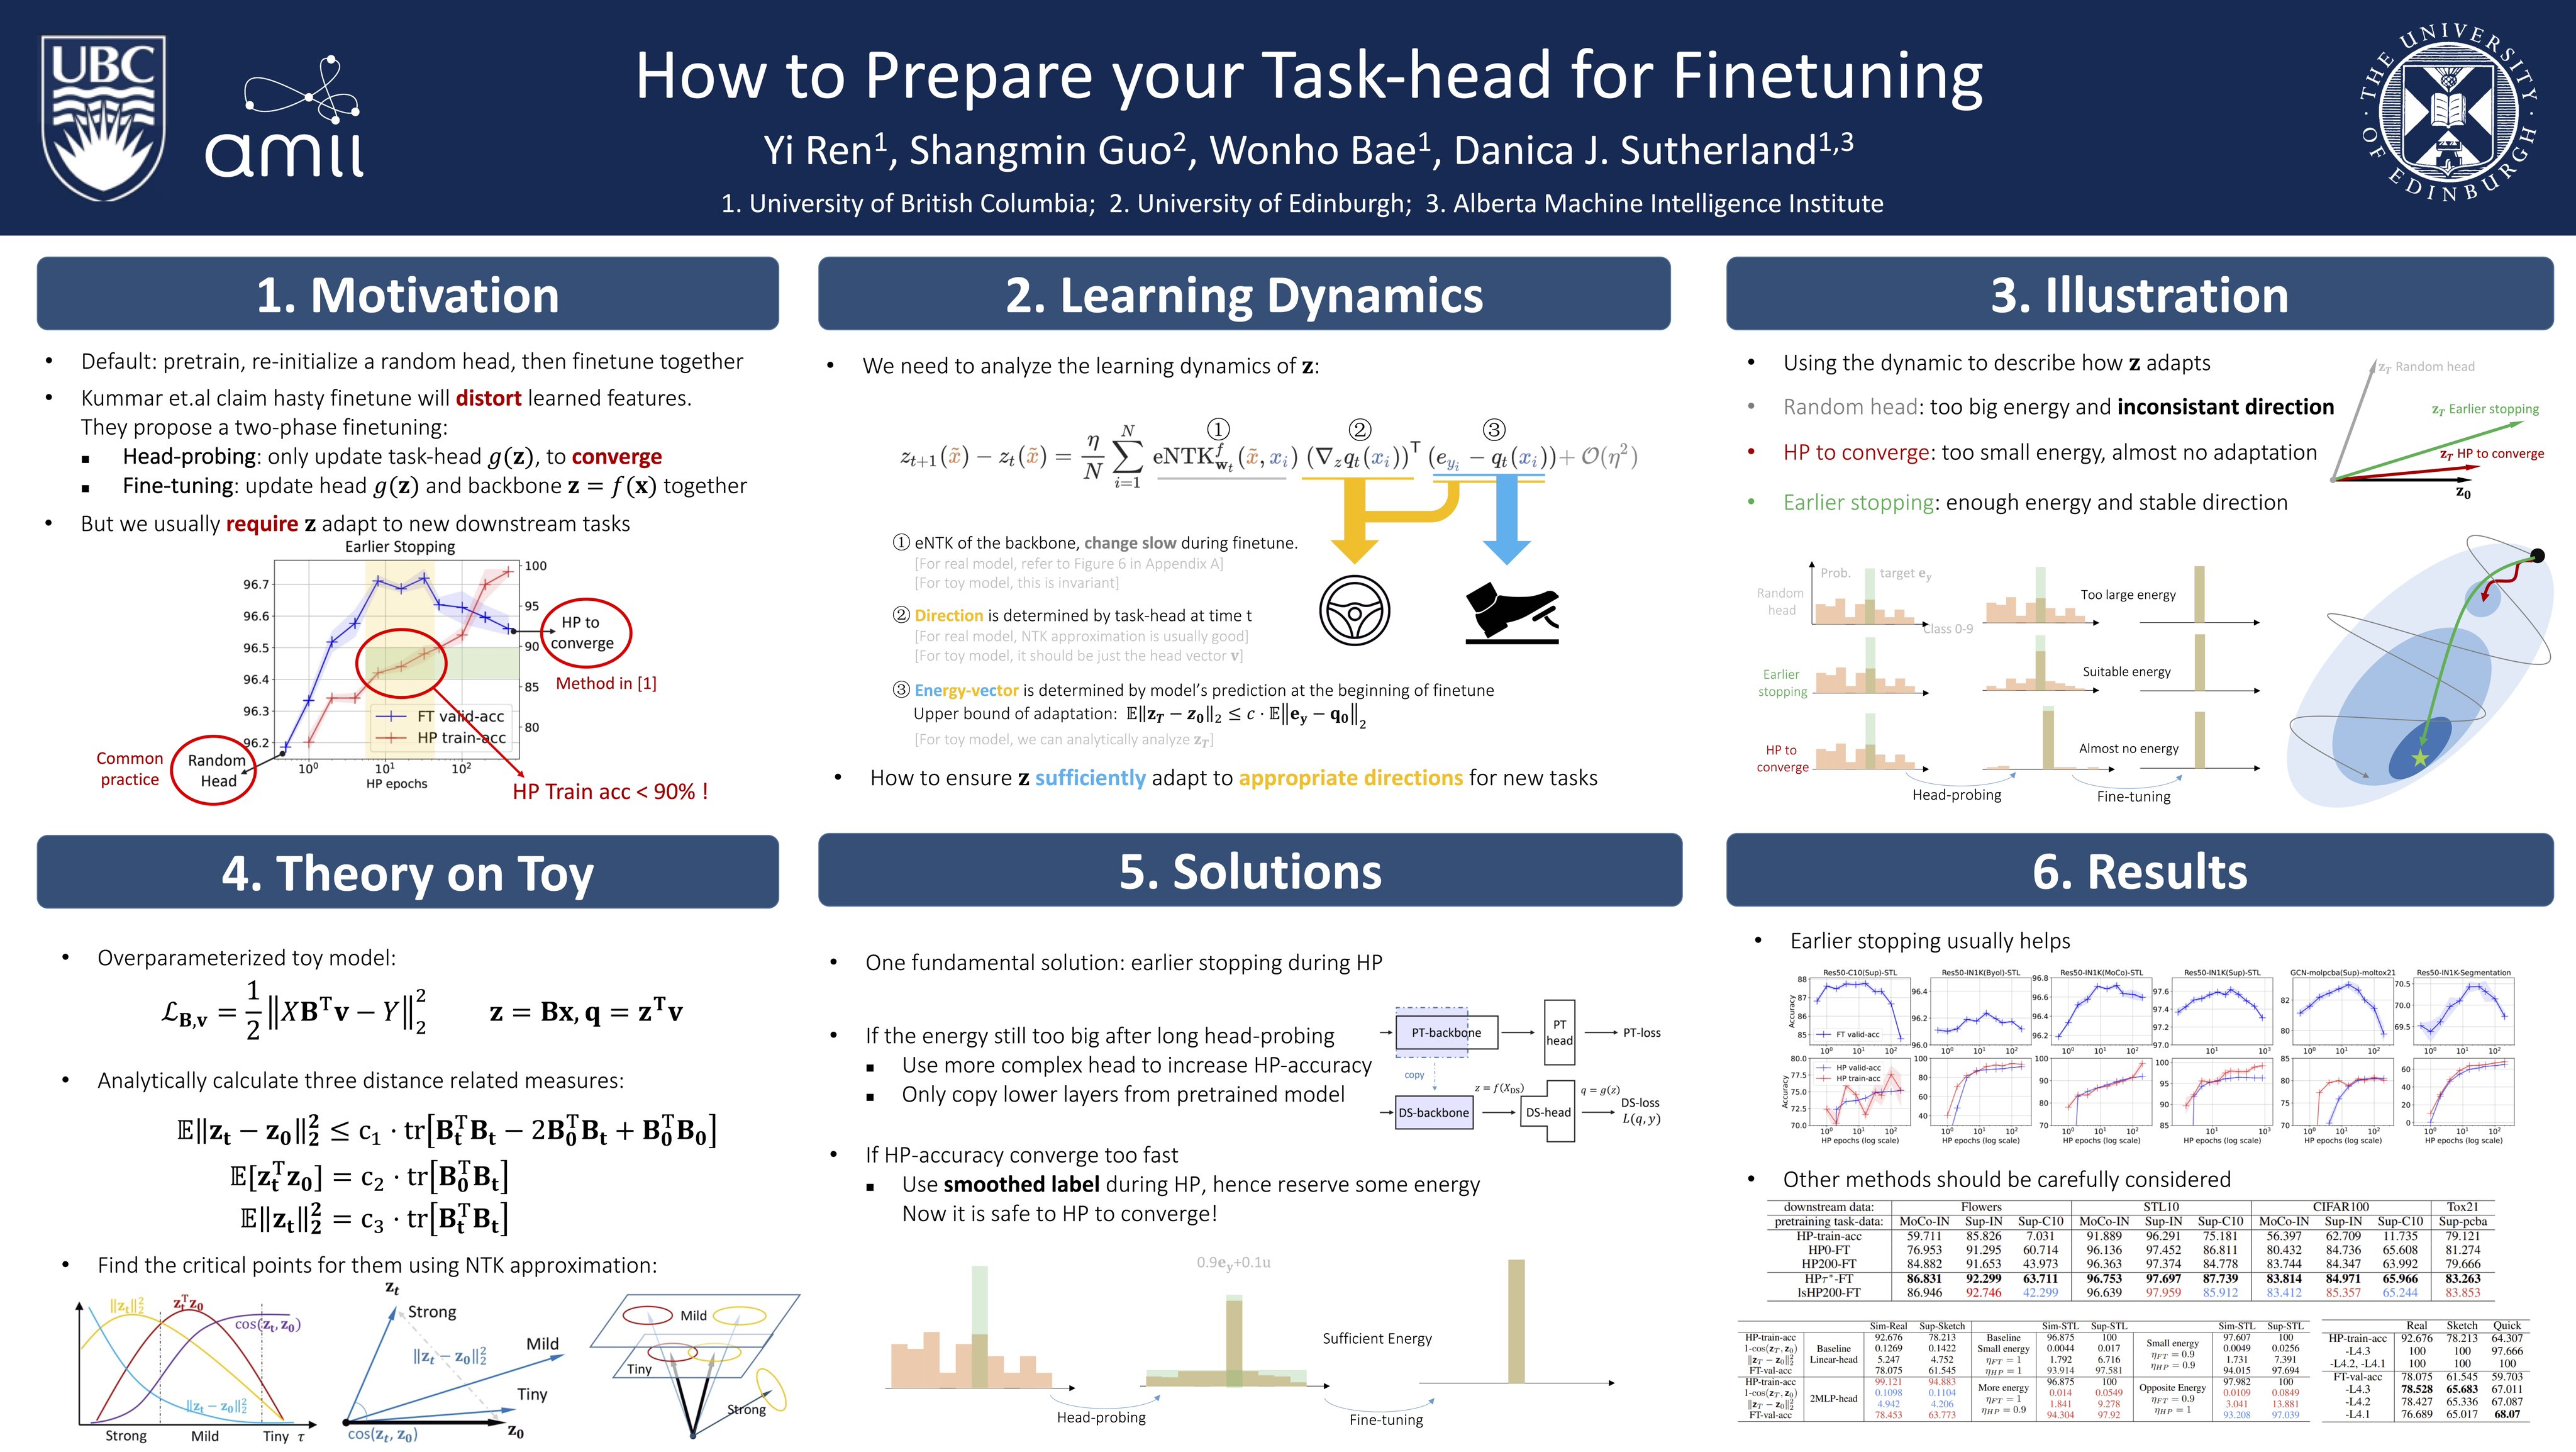
We have used it to find better supervisory signals (Ren et al., ICLR 2022), to design fine-tuning heads (Ren et al., ICLR 2023), and to explain what really happens to an LLM during finetuning (Ren et al., ICLR 2025). The same lens turns out to be surprisingly effective for RL post-training: it explains what negative gradients do to the output distribution (Deng et al., NeurIPS 2025), how token-level hidden rewards trade exploration against exploitation (Deng et al., ICLR 2026), and why GRPO collapses so readily in agentic search (Deng et al., ICML 2026).
I suspect these observations point at something more general: that compression and Occam's Razor are not merely descriptions of good models, but constraints on how learning has to work — a view put nicely in this talk on Compression for AGI.
Now: forgetting and continual learning
Lifelong (continual) learning lets AI systems keep adapting as new knowledge becomes available. Because learning inevitably interacts with what a model already knows, getting there requires a principled account of the different forms of forgetting — catastrophic forgetting, intentional unlearning, and time-dependent forgetting. We are working to uncover the mechanisms behind these phenomena across different learning algorithms and to bring them under one analytical framework, ultimately making such systems safer, more efficient and more capable.
Earlier: iterated learning
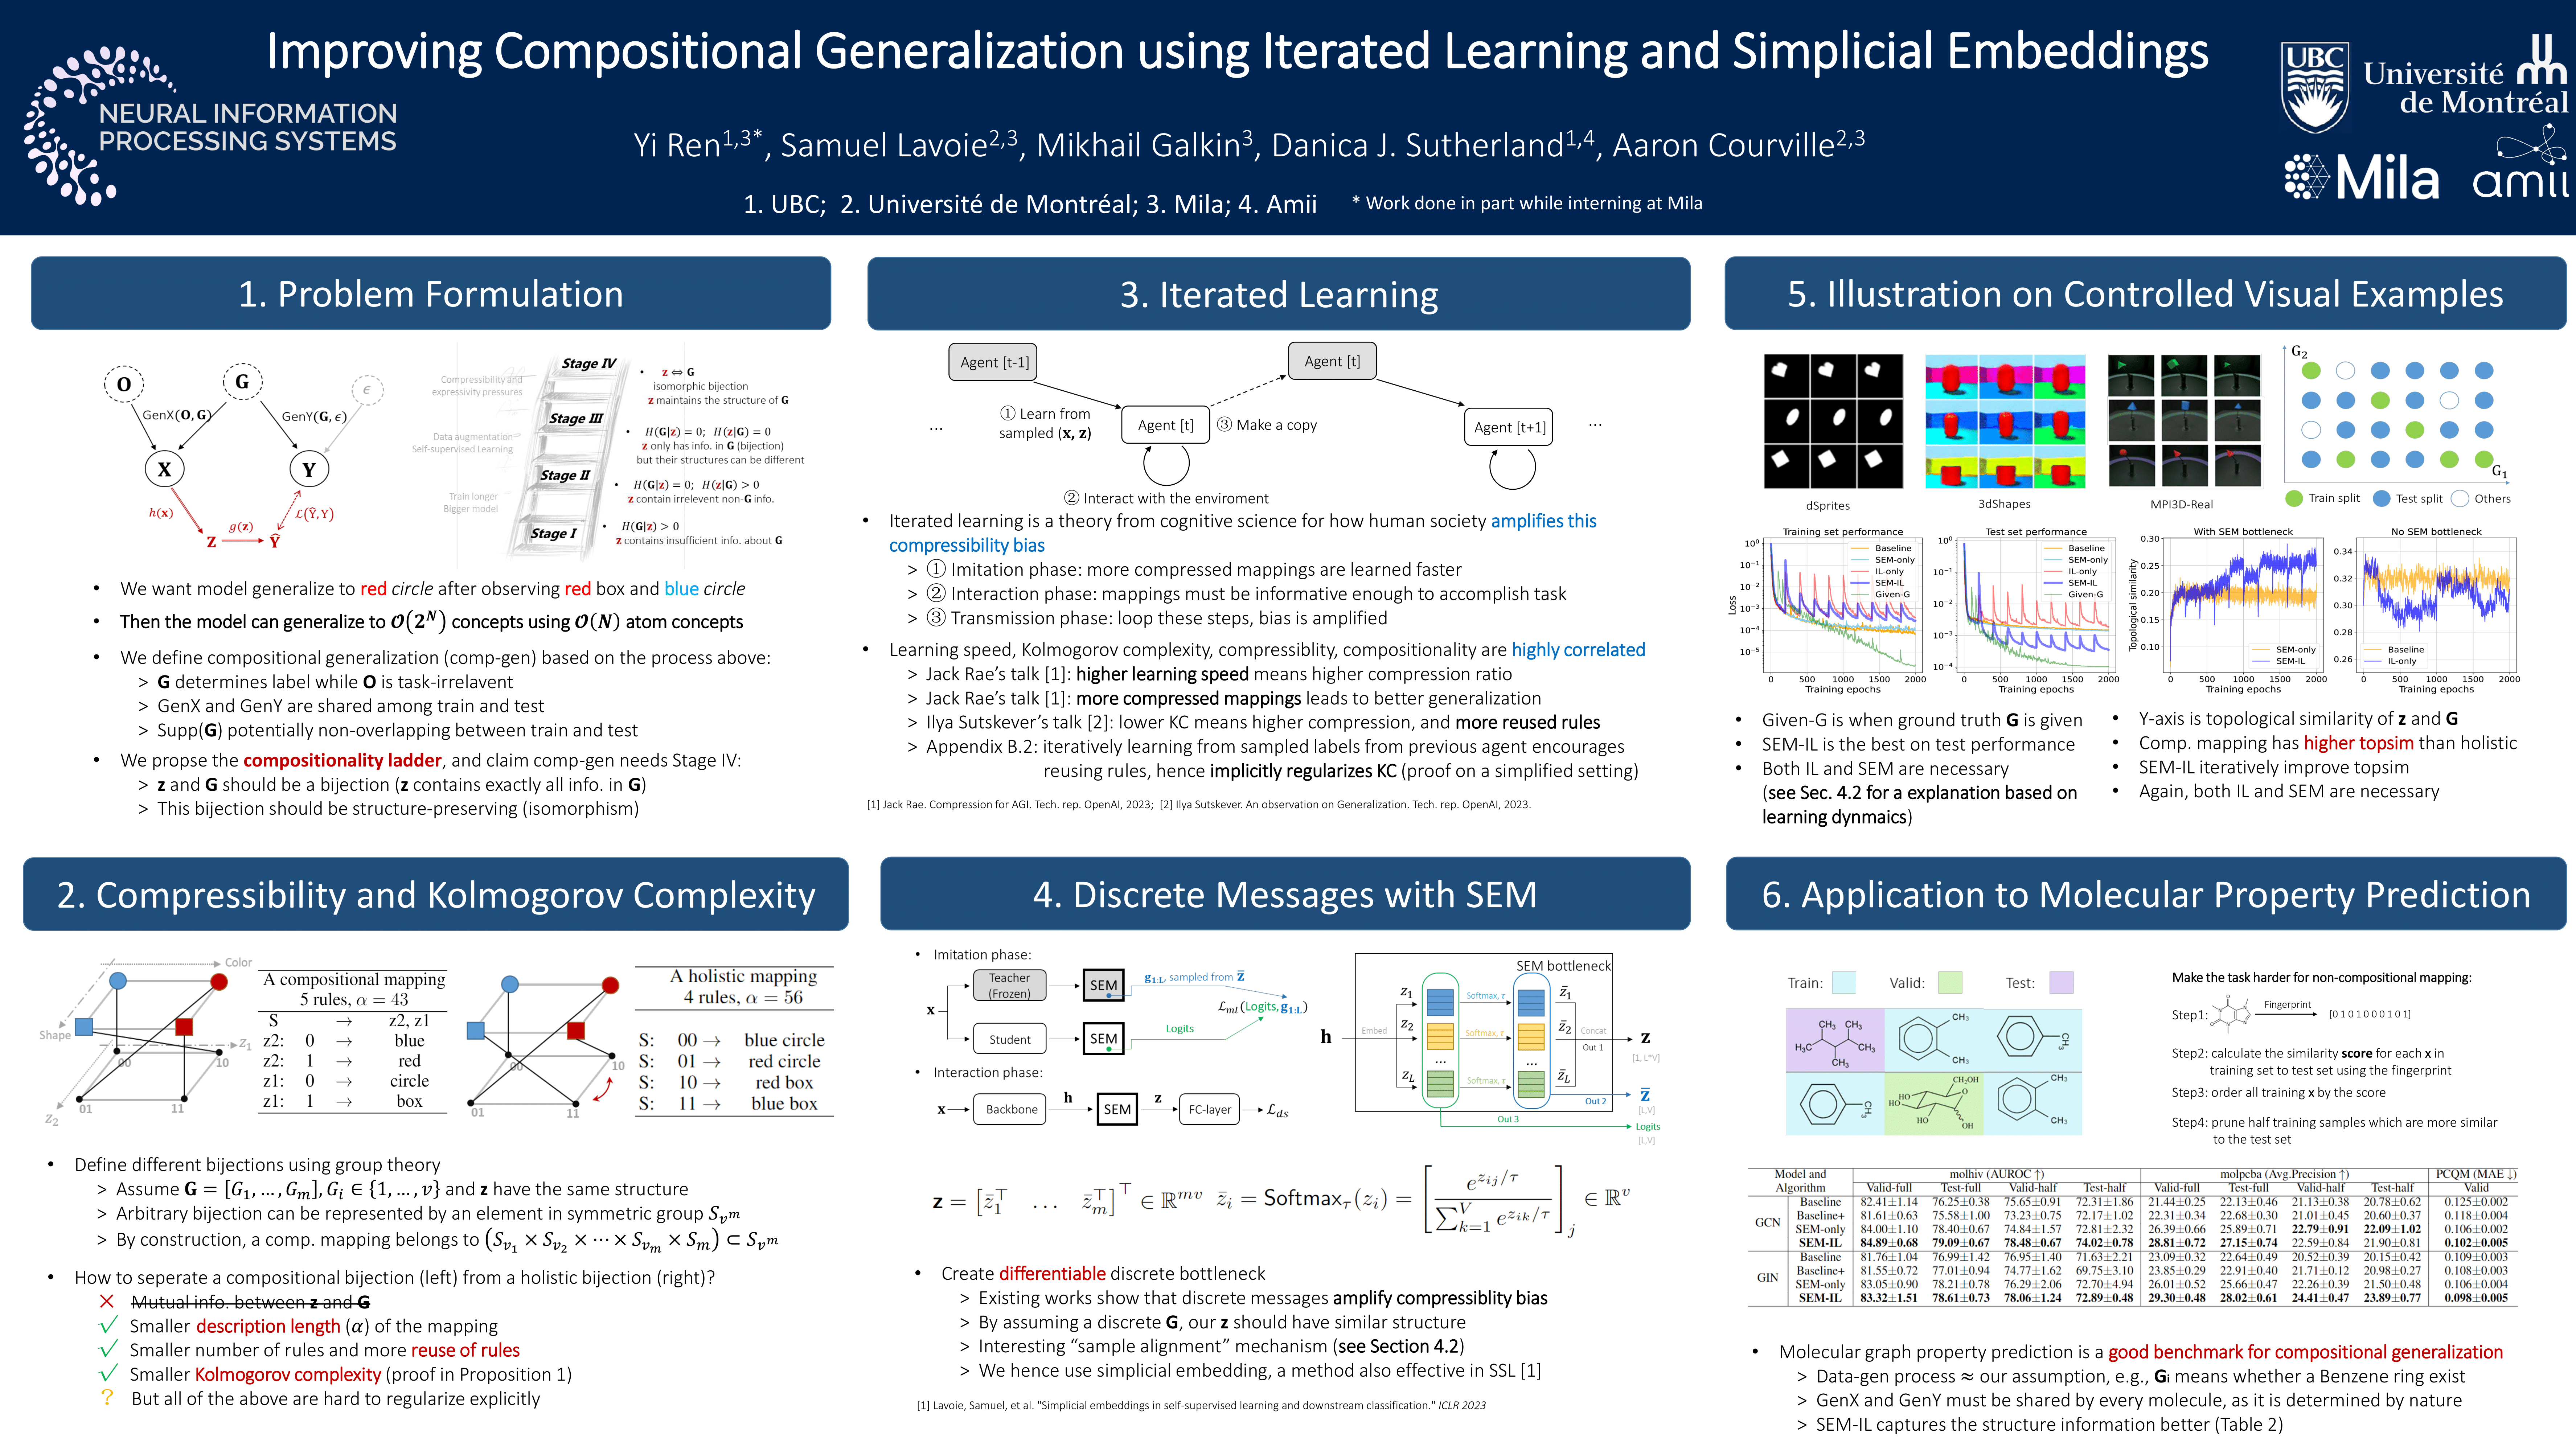
Before that I worked on iterated learning, an idea from cognitive science: a weak bias can be amplified generation after generation when each learner is trained on the output of the previous one. I started with emergent communication, where two agents have to invent a compositional language from scratch (Ren et al., ICLR 2020), then extended it to representation learning over vision, language and even molecular graphs during my visit to Aaron Courville's group at Mila (Ren et al., NeurIPS 2023). More recently we showed that the same framework partly explains how LLMs drift under repeated self-improvement, including diversity collapse and hidden bias amplification (Ren et al., NeurIPS 2024).
News
- 09/2026 happy to be selected as an Area Chair for ICLR. I hope I can do a good job.
- 04/2026 our paper LLDs (Lazy Likelihood Displacement introduced Death Spiral) has been accepted by ICML. It explains why GRPO collapses so easily in the tool-use case.
- 02/2026 arrived at Oxford, start a new journey
- 09/2025 passed the Ph.D. oral defense. Now I'm a doctor :-) (also dogtor and ducktor)
- 07/2025 our work (led by Wenlong Deng) "Token Hidden Reward: Steering Exploration-Exploitation in GRPO Training" has been selected as the Best Paper at the 2nd AI for Math Workshop @ ICML 2025.
- 04/2025 our work about learning dynamics and LLM's finetuning has been selected as one of the three Outstanding Paper Awards at ICLR 2025!
Talks
- 05/2026 Happy to share some understandings of the great paper "A Theory of Generalization in Deep Learning" by Elon Litman. Here is the notion page, any comments are welcome!
- 11/2025 Happy to share some interesting works about learning dynamics at different places (Slides)
- 07/2024 Happy to share some of my understandings about the Platonic Representation Hypothesis. (Slides)
- 03/2024 Happy to give a talk at Chalmers University of Technology about the application and understanding of neural iterated learning. (Slides)
Publications
Preprints:
-
Learning Dynamics of Continual Learning: A Unified View of Data Attribution, Forgetting, and Plasticity Loss
Yi Ren, Wenlong Deng, Guanzhe Hong, CL, Yarin Gal
arXiv preprint 2026 | code | page -
SimKO: Simple Pass@ K Policy Optimization
Ruotian Peng, Yi Ren, Zhouliang Yu, Weiyang Liu, Yandong Wen
arXiv preprint 2025 | pdf | code | page
Journal and Low-Acceptance-Rate Conference Papers:
-
On Group Relative Policy Optimization Collapse in Agent Search: The Lazy Likelihood-Displacement
Wenlong Deng, Yushu Li, Boying Gong, Yi Ren, Boying Gong, Christos Thrampoulidis, Xiaoxiao Li
ICML 2026 | pdf -
Token Hidden Reward: Steering Exploration-Exploitation in Group Relative Deep Reinforcement Learning
Wenlong Deng, Yi Ren, Yushu Li, Boying Gong, Danica J. Sutherland, Xiaoxiao Li, Christos Thrampoulidis
ICLR 2026 | pdf -
On the Effect of Negative Gradient in Group Relative Deep Reinforcement Optimization
Wenlong Deng, Yi Ren, Muchen Li, Danica J Sutherland, Xiaoxiao Li, Christos Thrampoulidis, Danica J. Sutherland
NeurIPS 2025 | pdf -
Learning Dynamics of LLM Finetuning
Yi Ren, Danica J. Sutherland
ICLR 2025 🏅 (Oral, Outstanding Paper Award, 3 out of 11672 submissions) | pdf | code | poster | slides -
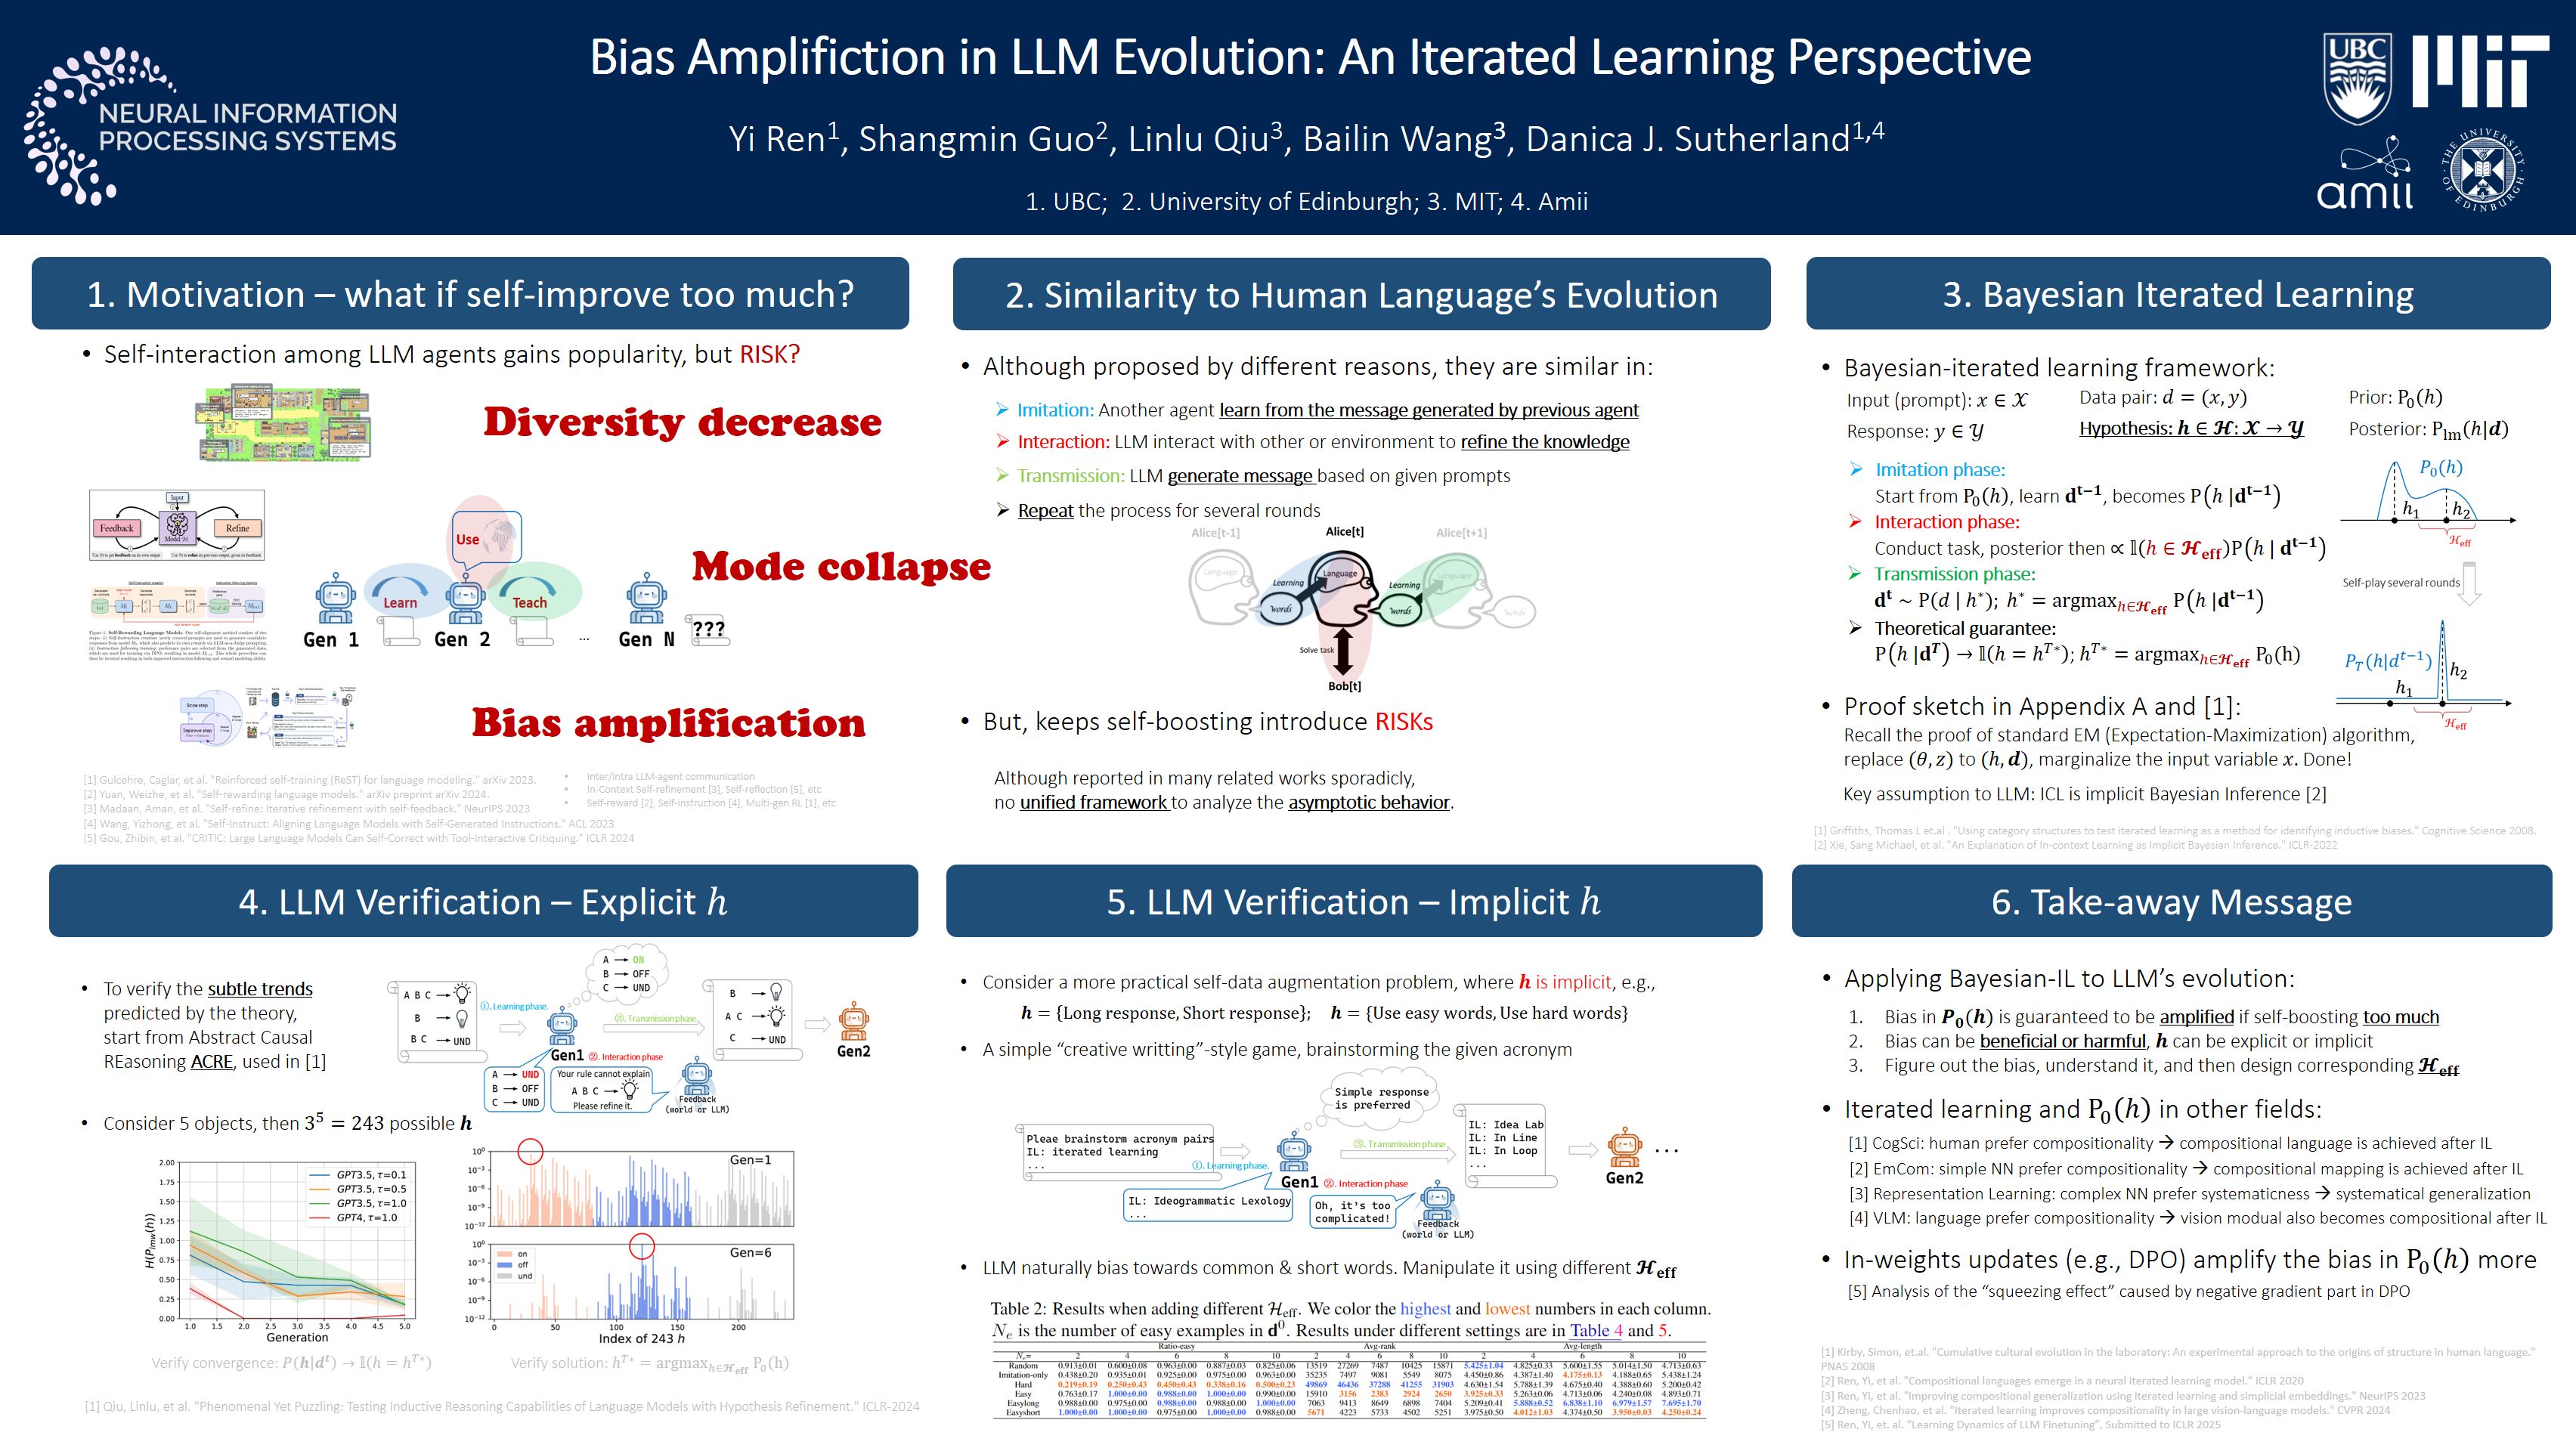
Bias Amplification in Language Model Evolution: An Iterated Learning Perspective
Yi Ren, Shangmin Guo, Linlu Qiu, Bailin Wang, Danica J. Sutherland
NeurIPS 2024 | pdf | code | poster -
AdaFlood: Adaptive Flood Regularization
Wonho Bae, Yi Ren, Mohamad Osama Ahmed, Frederick Tung, Danica J Sutherland, Gabriel L Oliveira
Transactions on Machine Learning Research (TMLR) 2024 | pdf -
lpNTK: Better Generalisation with Less Data via Sample Interaction During Learning
Shangmin Guo, Yi Ren, Stefano V. Albrecht, Kenny Smith
ICLR 2024 | pdf -
Improving Compositional Generalization using Iterated Learning and Simplicial Embeddings
Yi Ren, Samuel Lavoie, Mikhail Galkin, Danica J. Sutherland, Aaron Courville
NeurIPS 2023 | pdf | code | poster -
How to prepare your task head for finetuning
Yi Ren, Shangmin Guo, Wonho Bae, Danica J. Sutherland
ICLR 2023 | pdf | code | poster -
Better Supervisory Signals by Observing Learning Paths
Yi Ren, Shangmin Guo, Danica J. Sutherland
ICLR 2022 | pdf | code | poster -
Expressivity of Emergent Language is a Trade-Off between Contextual Complexity and Unpredictability
Shangmin Guo, Yi Ren, Kory Mathewson, Simon Kirby, Stefano V. Albrecht, Kenny Smith
ICLR 2022 | pdf | code | workshop-version -
Compositional languages emerge in a neural iterated learning model
Yi Ren, Shangmin Guo, Matthieu Labeau, Shay B. Cohen, Simon Kirby
ICLR 2020 | pdf | code | workshop-version
Ph.D. Thesis:
Workshop Presentations:
-
Token Hidden Reward: Steering Exploration-Exploitation in GRPO Training
Wenlong Deng, Yi Ren, Danica J. Sutherland, Xiaoxiao Li, Christos Thrampoulidis,
AI for Math@ICML 2025 (Oral, Best Paper Award) -
On the Effect of Negative Gradient in Group Relative Deep Reinforcement Optimization
Wenlong Deng, Yi Ren, Muchen Li, Danica J. Sutherland, Xiaoxiao Li, Christos Thrampoulidis
AI for Math@ICML 2025 | pdf -
Understanding Simplicity Bias towards Compositional Mappings via Learning Dynamics
Yi Ren, Danica J. Sutherland
Compositional Learning @NeurIPS 2024 | pdf | code | poster -
Economics arena for large language models
Shangmin Guo, Haoran Bu, Haochuan Wang, Yi Ren, Dianbo Sui, Yuming Shang, Siting Lu
Language Gamification @NeurIPS 2024 | pdf -
The Emergence of Compositional Languages for Numeric Concepts Through Iterated Learning in Neural Agents
Shangmin Guo, Yi Ren, Serhii Havrylov, Stella Frank, Ivan Titov, Kenny Smith
EmeCom @NeurIPS 2019 | pdf